The small files problem in Spark and Delta Lake: what causes it, how to detect it, and how to fix it with ..
Learn Adaptive Query Execution (AQE) in Spark in simple words: how it merges small partitions, switches ..
Why are Python UDFs slow in PySpark, and when should you use a Pandas UDF or a built-in function instead? ..
Learn narrow vs wide transformations in Spark in simple words: shuffle, stages, lazy evaluation, PySpark ..
Learn partitioning vs bucketing in Spark in simple words, with PySpark and SQL code, a comparison table, ..
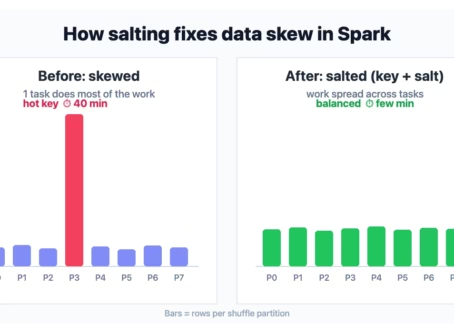
Learn cache vs persist in PySpark in simple words, with code, storage levels, Spark SQL caching, common ..
cache() vs persist() in PySpark explained in simple words: default storage levels for RDD, DataFrame ..
Learn data skew in Spark in simple words: how to detect it, AQE skew join settings, broadcast, NULL keys ..
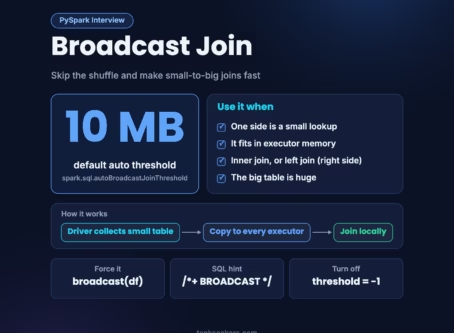
Learn broadcast join in PySpark in simple words: how it works, the 10 MB threshold, SQL hints, when not to use it, plus ..
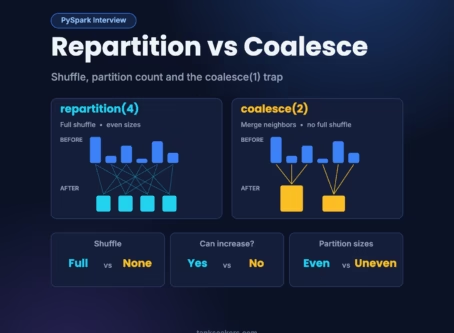
Learn repartition vs coalesce in PySpark in simple words, with code, a comparison table, the coalesce(1) ..
End of content
No more posts to load